We ran a scanned page through the exact engine behind FileFlip's PDF-to-Word route. On a PDF with a real text layer, MuPDF pulled back 361 characters, the whole paragraph, correctly spelled. On a PDF that was only a picture of the same page, it pulled back zero, and Pandoc wrote out a Word document with no text and no picture in it at all. Getting words out of that second file needs a completely different piece of software, and it's the one thing we don't ship.
Should you convert a scanned PDF, or run OCR first?
Try selecting a word on the page. That one test tells you which job you actually need.
- Text highlights when you drag over it. The PDF already has a text layer. Convert PDF to DOCX directly and every character comes with it.
- Nothing highlights, no matter where you click. The page is a picture, not text. Run OCR on it first (tools below), then convert whatever that produces.
- You only need to look at the page, not edit it. Convert PDF to PNG and keep it as an image. Nothing gets invented, nothing gets guessed.
What happens when FileFlip converts a scanned PDF?
It depends entirely on the route. One keeps every pixel. The other comes back empty.
| Route | What FileFlip runs | On a scanned page |
|---|---|---|
| PDF → PNG | MuPDF renders the page to an image | The full page, as a picture, at about 144 DPI |
| PDF → DOCX | MuPDF looks for a text layer, then Pandoc writes the document | No text layer to find, so the document comes back with no text and no picture |
What does OCR actually do to a scanned page?
It looks at the shapes on the page and guesses which letters they are, one region at a time, then strings the guesses into words with a language model to break ties.
A typical engine binarizes the image to black and white, finds lines and word boxes on the page, and runs a trained classifier over each one to score which character it most resembles. None of that touches anything a decoder would call "the data": there is no PDF text object, no font, no character code anywhere in a scanned page for a converter to find. The classifier is inventing characters from pixel shapes, informed by a dictionary that nudges an ambiguous guess toward a real word. That's also why OCR needs a language pack: the dictionary and the letter shapes it expects are both language-specific.
Why isn't OCR the same operation as converting a file?
Because a conversion only moves data that's already in the file, and a scanned page has no text in it to move.
FileFlip already says this about the routes where it applies. Convert a photo into a PDF, PNG to PDF for instance, and the page's own caveat reads: "the picture is placed in the document as a picture; no text is recognised out of it." Going the other way, from a scanned PDF to DOCX, the app never gets the chance to make that promise, because there's no code path for OCR anywhere in the document worker to run.
- PDF with a text layer361 characters, the whole paragraph
- Scanned page, image only0 characters. No text, no picture, just page formatting.
Same paragraph rendered onto an identical page, run through FileFlip's own PDF-to-DOCX pipeline: MuPDF 1.28.2 and Pandoc 3.10.2, the same engines the worker embeds. The only thing that changed between the two runs was whether the source PDF carried a text layer.
That zero is not a rounding error or a bad setting. The resulting DOCX's document.xml held 906 bytes, and every one of them was a bookmark and a section properties block Pandoc writes into any document. The text-layer version's document.xml ran 7,788 bytes, almost all of it the paragraph itself in 65 separate text runs. A conversion is deterministic: the same PDF produces the same output every time, because it's reading bytes that were already there. OCR is a statistical guess, and the next section shows what that costs.
What does FileFlip do with a scanned PDF instead?
It renders the page as a picture, honestly, rather than guessing at text that was never there.
Convert PDF to PNG and MuPDF rasterizes each page at roughly 144 DPI, the same "fixed-render-scale" it uses for any PDF page, in opaque RGB. That's the accurate answer for a scanned document: you get back exactly what a scanner produced, viewable, croppable, droppable into another document, with nothing added and nothing missing. It just isn't searchable, because it was never text to begin with.
Why can't you just trust what OCR gives back?
Because it can be confidently wrong, and nothing in the plain output flags which words to double check.
We rendered the same 48-word paragraph as a clean, sharp image and ran Tesseract 5.5.3 on it: zero errors, every word correct. We then blurred and downscaled the identical image, same text, same font, same page, nothing else changed, and ran it again. Tesseract got 13 of the 48 words wrong, a 27% word error rate, and several of the wrong words scored higher confidence than some of the correct ones: "date" misread as "Gate" scored 88% confidence, and "six" misread as "sa" scored 83%. The correctly read word "weight" scored 0%.
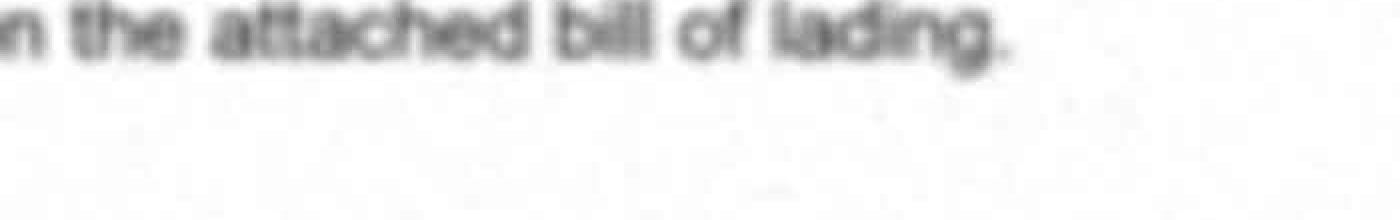
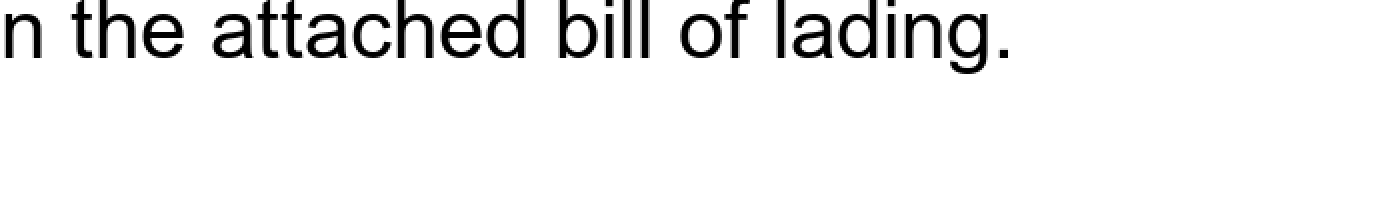
The same crop, magnified 2x from a 700x110 pixel region of a generated 1700x2200 page, before and after Gaussian blur, noise, and a downscale-and-back-up pass on the right image. Text content, font and layout are identical; only image quality changed. Tesseract read the left version with zero errors and misread "bill" as "bal" on the right.
A word processor's OCR-derived text file carries no marker for which words the engine was unsure about. It reads exactly as confidently as the words it got right.
Which tools actually do OCR well?
None of them are FileFlip, and each one trades off differently between accuracy, privacy and cost.
| Tool | Runs | Cost | Worth knowing |
|---|---|---|---|
| Tesseract | Locally, command line | Free, open source | No interface of its own; other apps embed it. |
| Apple Live Text | Locally, on device | Free, built into macOS and iOS | Select and copy text straight out of a photo or PDF page. |
| Microsoft PowerToys Text Extractor | Locally, on device | Free, open source | Needs a language pack installed; Microsoft's own docs say to proofread the result. |
| Google Drive | Uploaded to Google | Free with a Google account | 2 MB file limit, and the output is a plain-text Google Doc with the original layout gone. |
When is running OCR not worth it?
When the document is short enough to retype, sensitive enough that an upload is the wrong move, or the scan itself is bad enough that OCR has nothing good to work from.
A one-page form you'll read once doesn't need a separate OCR pass; open the PNG and read it. A payslip, a medical letter or anything else you wouldn't paste into a public form is worth running through something that stays on your machine, Tesseract, Live Text or PowerToys, rather than a browser-based tool that uploads the file first. And Tesseract's own FAQ says plainly that it's "designed for printed text" and "won't work very well" on handwriting, which holds for most general-purpose OCR: a handwritten scan usually needs a tool built for that specific job, not a typeset-text engine pointed at cursive.
Common questions
Can FileFlip run OCR on a scanned PDF?
No. FileFlip's document worker extracts text that's already in a file, or renders pages as images; it never runs a recognition model over pixels. Run OCR yourself first with one of the tools above, then convert the text it produces.
How do I tell if a PDF is a scan or a real document?
Try to select a word. If it highlights, there's a text layer underneath and FileFlip's converters can read it directly. If nothing highlights no matter where you click, the page is an image with no text in the file at all.
Is there a free way to OCR a PDF?
Yes. Tesseract, Apple's Live Text and Microsoft's PowerToys Text Extractor are all free and run on your own machine. Google Drive's OCR is also free but uploads the file to convert it, and caps input at 2 MB.
Will OCR ever be completely accurate?
Not reliably. Our own test above went from 0% to 27% word error rate on the same text with nothing but image quality changed, and general OCR engines like Tesseract aren't built to handle handwriting at all. Treat any OCR output as a first draft to proofread, not a finished transcript.
Convert between them
FileFlip converts PDF to PNG and PDF to DOCX in your browser, on a WebAssembly build of MuPDF, the same way every conversion here runs: nothing is uploaded, there's no account, and the file never leaves your machine. For a scan, that means the picture route is honest and the text route needs OCR run first, somewhere else, before there's any text for FileFlip to touch. For the format details, see the PDF, DOCX and PNG format references. For what else a conversion can quietly drop even when there's no scanning involved, see what a conversion actually costs you.
How we measured this
- Text extraction: a 48-word paragraph was set as a PDF with a real text layer (via macOS's
cupsfiltertext-to-PDF path) and, separately, rendered as a 1700×2200 PNG and wrapped in a PDF as a single image with no text layer, both one page. Both were run throughmutool convert -F html, MuPDF 1.28.2's HTML writer, which is the same step (to-html) FileFlip'spdf>docxroute uses before handing the result to Pandoc. The resulting HTML was converted to DOCX with Pandoc 3.10.2, matching the 3.10 buildpandoc-wasmembeds, using the same--standaloneflag the worker calls. Character counts were taken from<w:t>runs in each DOCX'sword/document.xml. - OCR accuracy: the same 1700×2200 PNG was OCR'd with Tesseract 5.5.3, then blurred (
-blur 0x2.4), given Gaussian noise (-attenuate 0.5) and downscaled to 20% and back to 100% with ImageMagick 7.1.2, keeping the canvas, font, and text identical, and OCR'd again. Word error rate is Levenshtein distance between the lowercased word lists of the ground truth and the OCR output, divided by the ground-truth word count. Per-word confidence came from Tesseract's TSV output mode. - Caveat: this is a synthetically blurred render, not a phone photo of a real page, so it isolates image quality as the only variable. A real scan usually adds skew, shadows and a crease, which would move the error rate around rather than necessarily lower it.
- Rendering: the page image itself used ImageMagick 7.1.2 with a system Arial font at 42pt on a 1700×2200 canvas, and the "no-ocr" caveat text was read directly from the pair-facts table that drives FileFlip's own conversion pages.